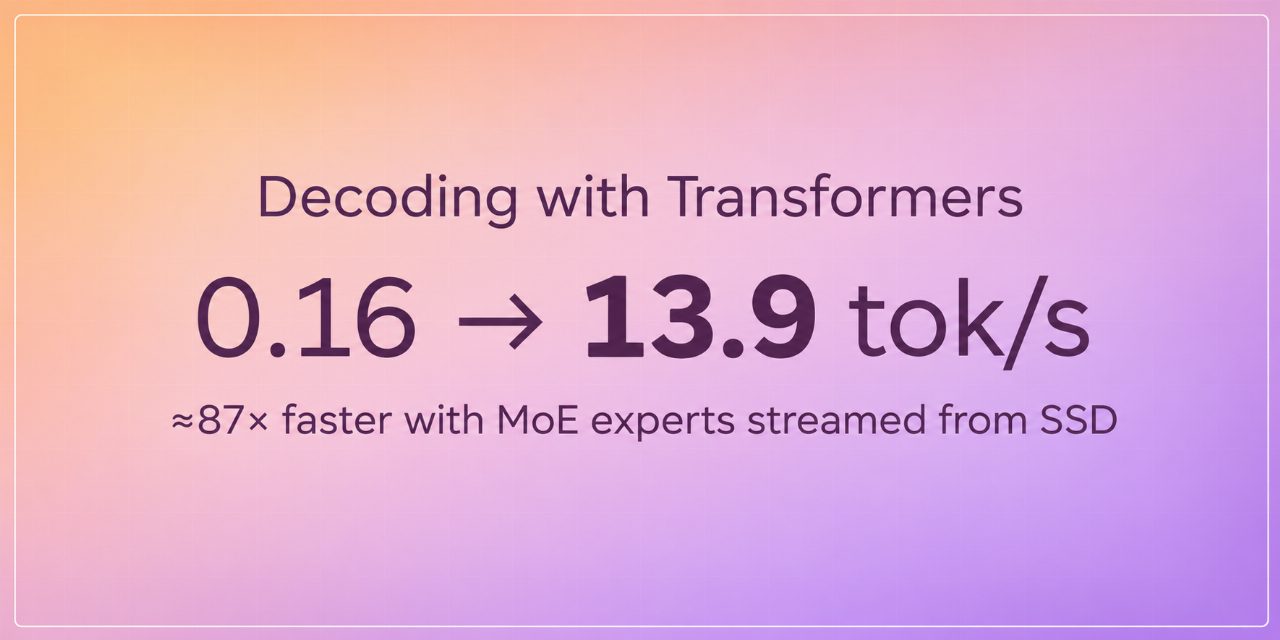
Tarek Ziadé tests running the 180B parameter Qwen3.8 model on a 32GB MacBook M5 using Hugging Face Transformers. The setup streams experts from SSD to get within 6% of Strata performance. This approach works when models exceed unified memory limits by treating disk as an expert cache.
It is worth trying if you need local coding agents on low-RAM Macs and accept slower speeds than VRAM-resident models. The code is fully AI-generated and requires significant setup effort. It does not replace high-end GPUs for latency-sensitive real-time work.
more: https://huggingface.co/blog/moe-expert-streaming
my other side: ivo.blogspot.com


Leave a Reply