C99 engine runs 2.78T parameter model on CPU

21 09 2026
C99 engine runs 2.78T parameter model on CPU

This is a portable C99 inference engine for the Kimi K3 2.78-trillion-parameter model. It runs on a standard CPU with 8 GB of RAM, using no BLAS, framework, or GPU. The entire engine is 176 KB, and it streams the 1.56 TB checkpoint from disk to keep peak memory usage low.

It is worth looking at if you want to understand how to run massive models without heavy dependencies, but do not expect interactive speed. On an 8 GB laptop, generation takes 26.5 seconds per token because the model streams from disk every step. It is a proof of concept for resource-constrained environments, not a replacement for GPU-accelerated inference.

more: https://github.com/FareedKhan-dev/kimi-k3-in-c

my other side: ivo.blogspot.com


Graft builds local code graphs for coding agents

21 09 2026
Graft builds local code graphs for coding agents

Graft is a CLI that generates a folder of linked markdown files to bridge coding agents to your codebase. It claims to reduce tool calls by 46 percent and token usage by 42 percent compared to cold starts. The graph acts as a local, regenerable cache that updates against the working tree in milliseconds.

It is worth trying if you use Claude Code and want to cut latency without adding a database dependency. The catch is that it relies on LLMs for summaries, so you need a compatible API key. It is not for teams that refuse to run external tools in their dev environment.

more: https://github.com/trailhq/Graft

my other side: ivo.blogspot.com


Hypit lets coding agents generate video workflows

21 09 2026
Hypit lets coding agents generate video workflows

Hypit is a Node.js tool that extends CLI agents like Claude Code and Codex to create videos. It uses a script-based language where visual elements are anchored to spoken words, not timestamps. A drop-in video can be cloned into a reusable workflow, or agents can build new ones from templates and descriptions.

The tool itself is free, but you still pay for the AI models used for footage and images. It requires a capable coding agent and some configuration for API connections, making it less suitable for users who want a simple GUI without touching code.

more: https://github.com/hypit-ai/hypit

my other side: ivo.blogspot.com


FreeToken runs 290B MoE models on consumer PCs

21 09 2026
FreeToken runs 290B MoE models on consumer PCs

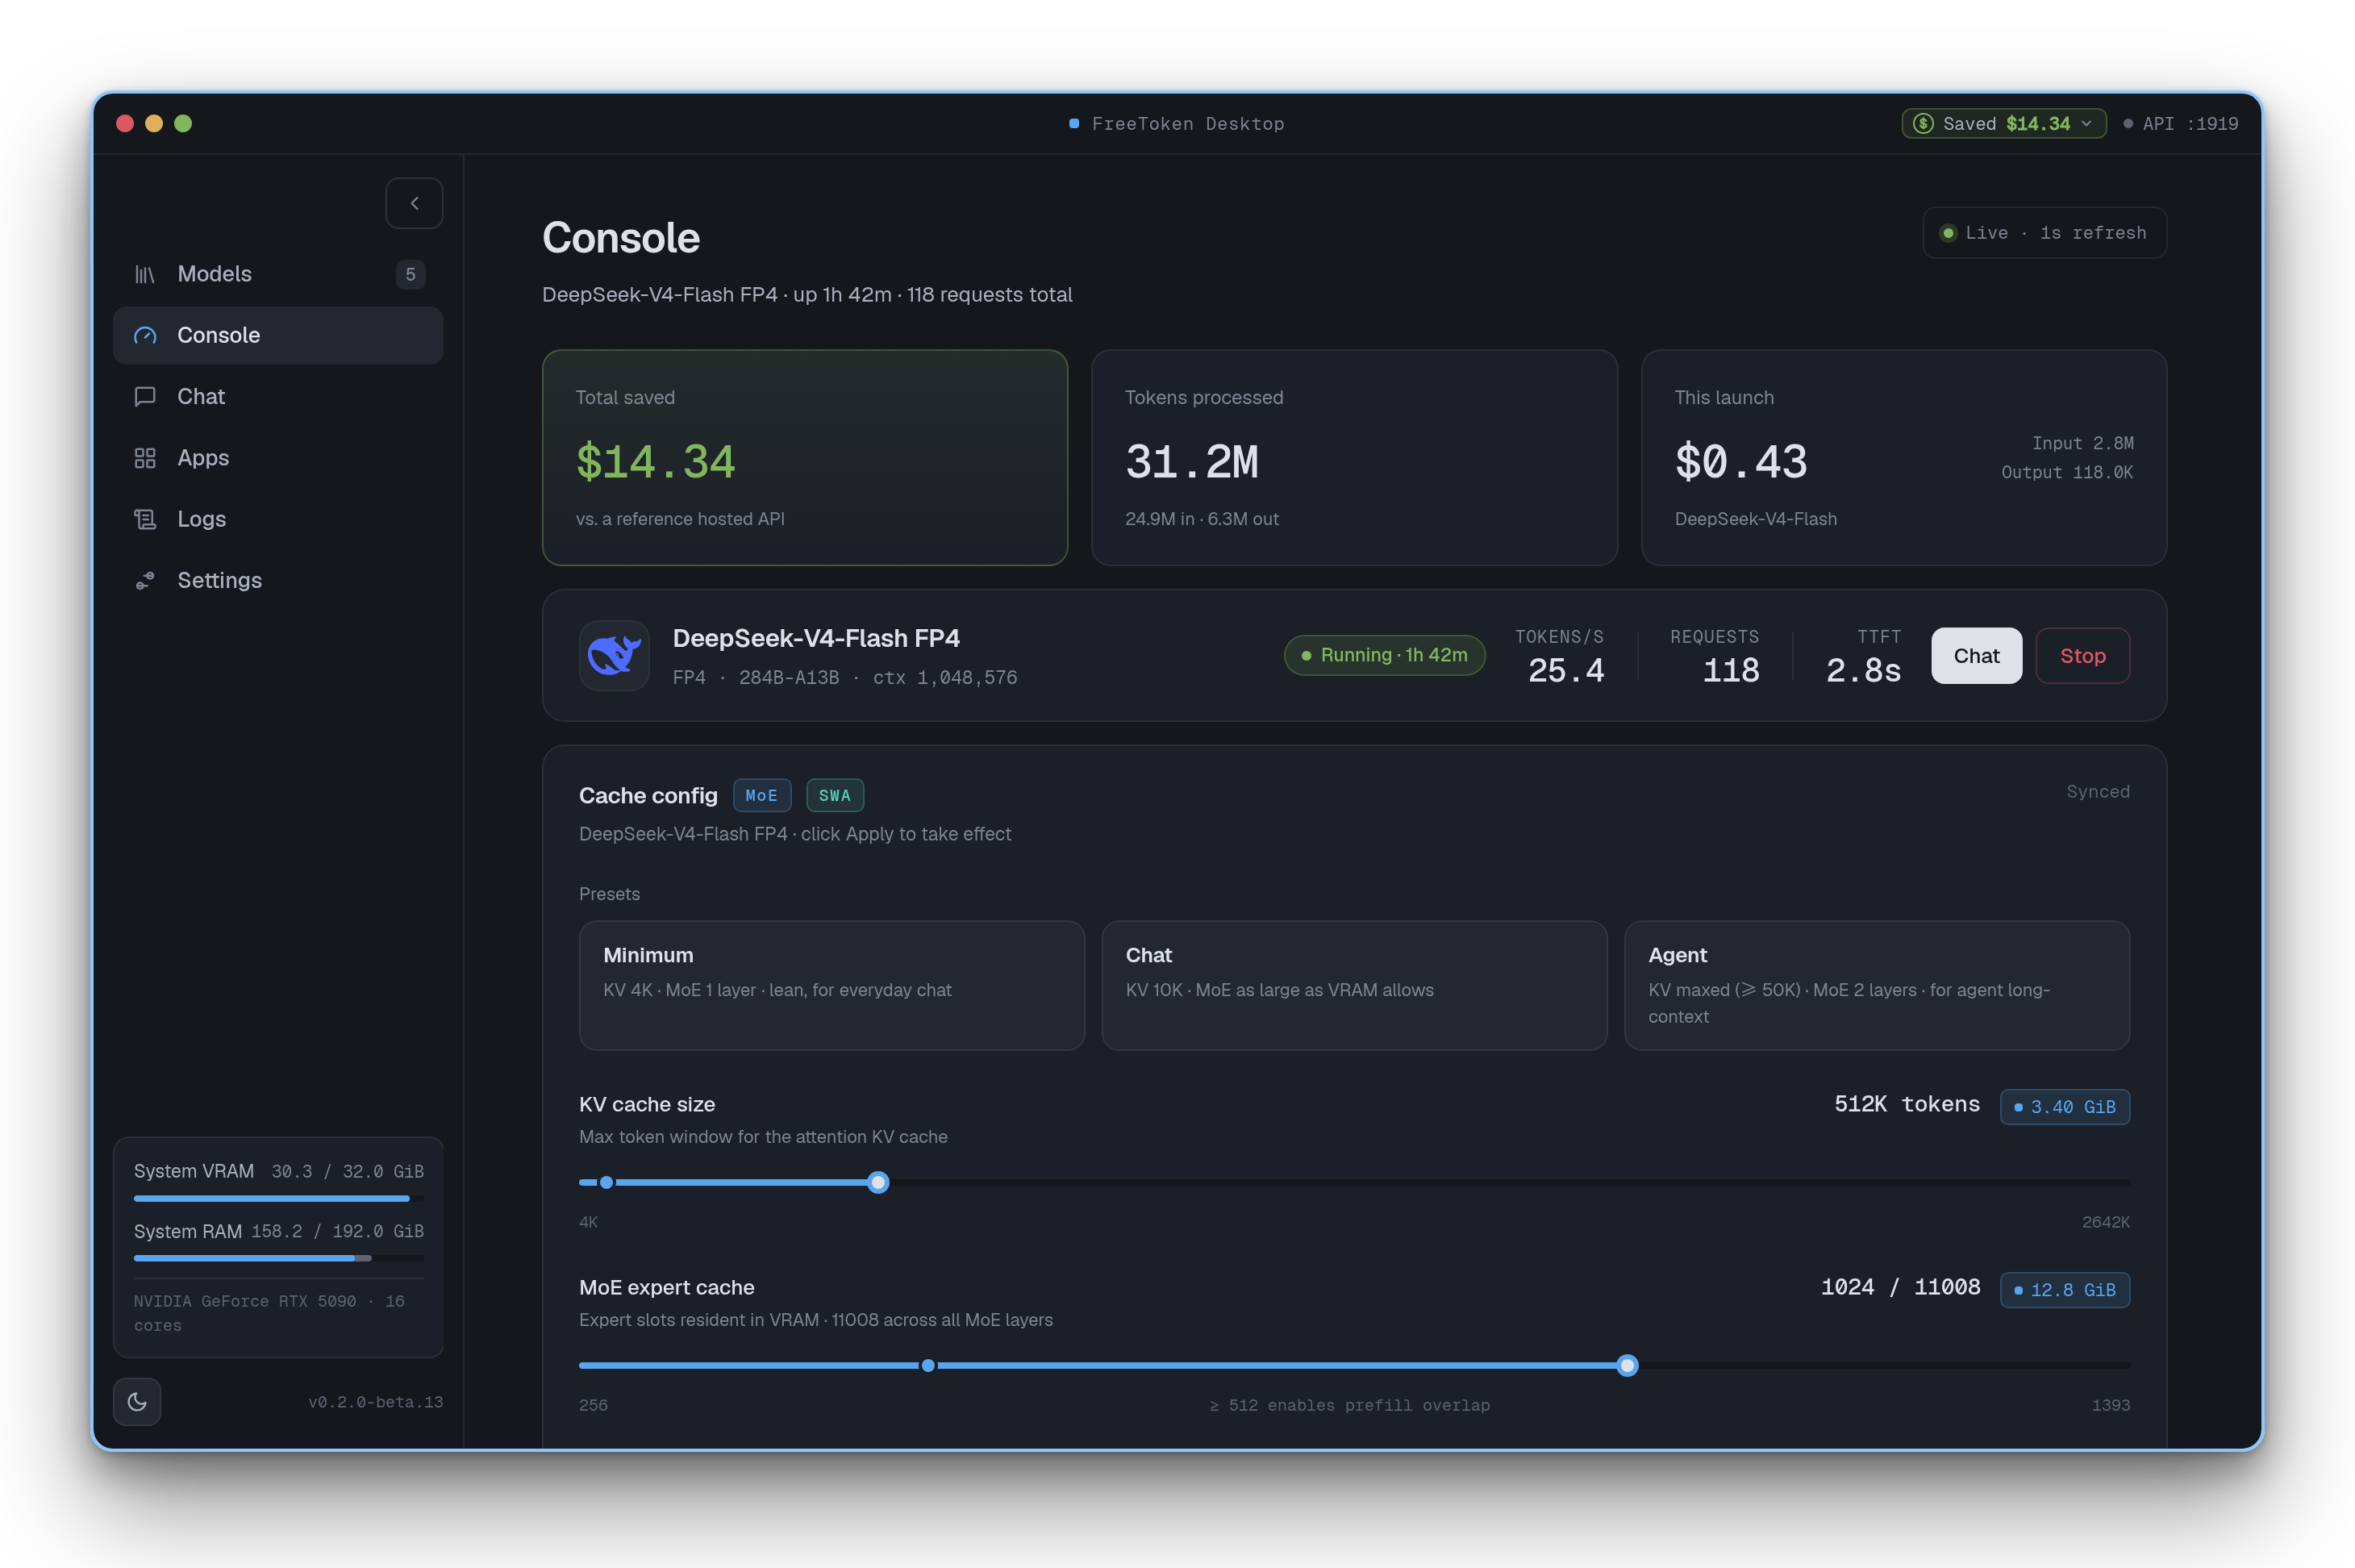
FreeToken is an edge-native inference engine designed to serve frontier-scale Mixture-of-Experts models on personal hardware. It unifies GPU, CPU, and host memory into a single elastic platform to achieve interactive speeds for 290B+ parameter models. A desktop app is available for Windows and Linux to handle the initial setup and tuning.

It is worth a look if you have high-end consumer hardware and need local access to large MoE models without a datacenter cluster. The project is young and relies on a complex hardware abstraction, so expect some configuration friction. It is not a drop-in replacement for production-grade serving stacks like vLLM in a cloud environment.

more: https://github.com/FlashML-org/FreeToken

my other side: ivo.blogspot.com