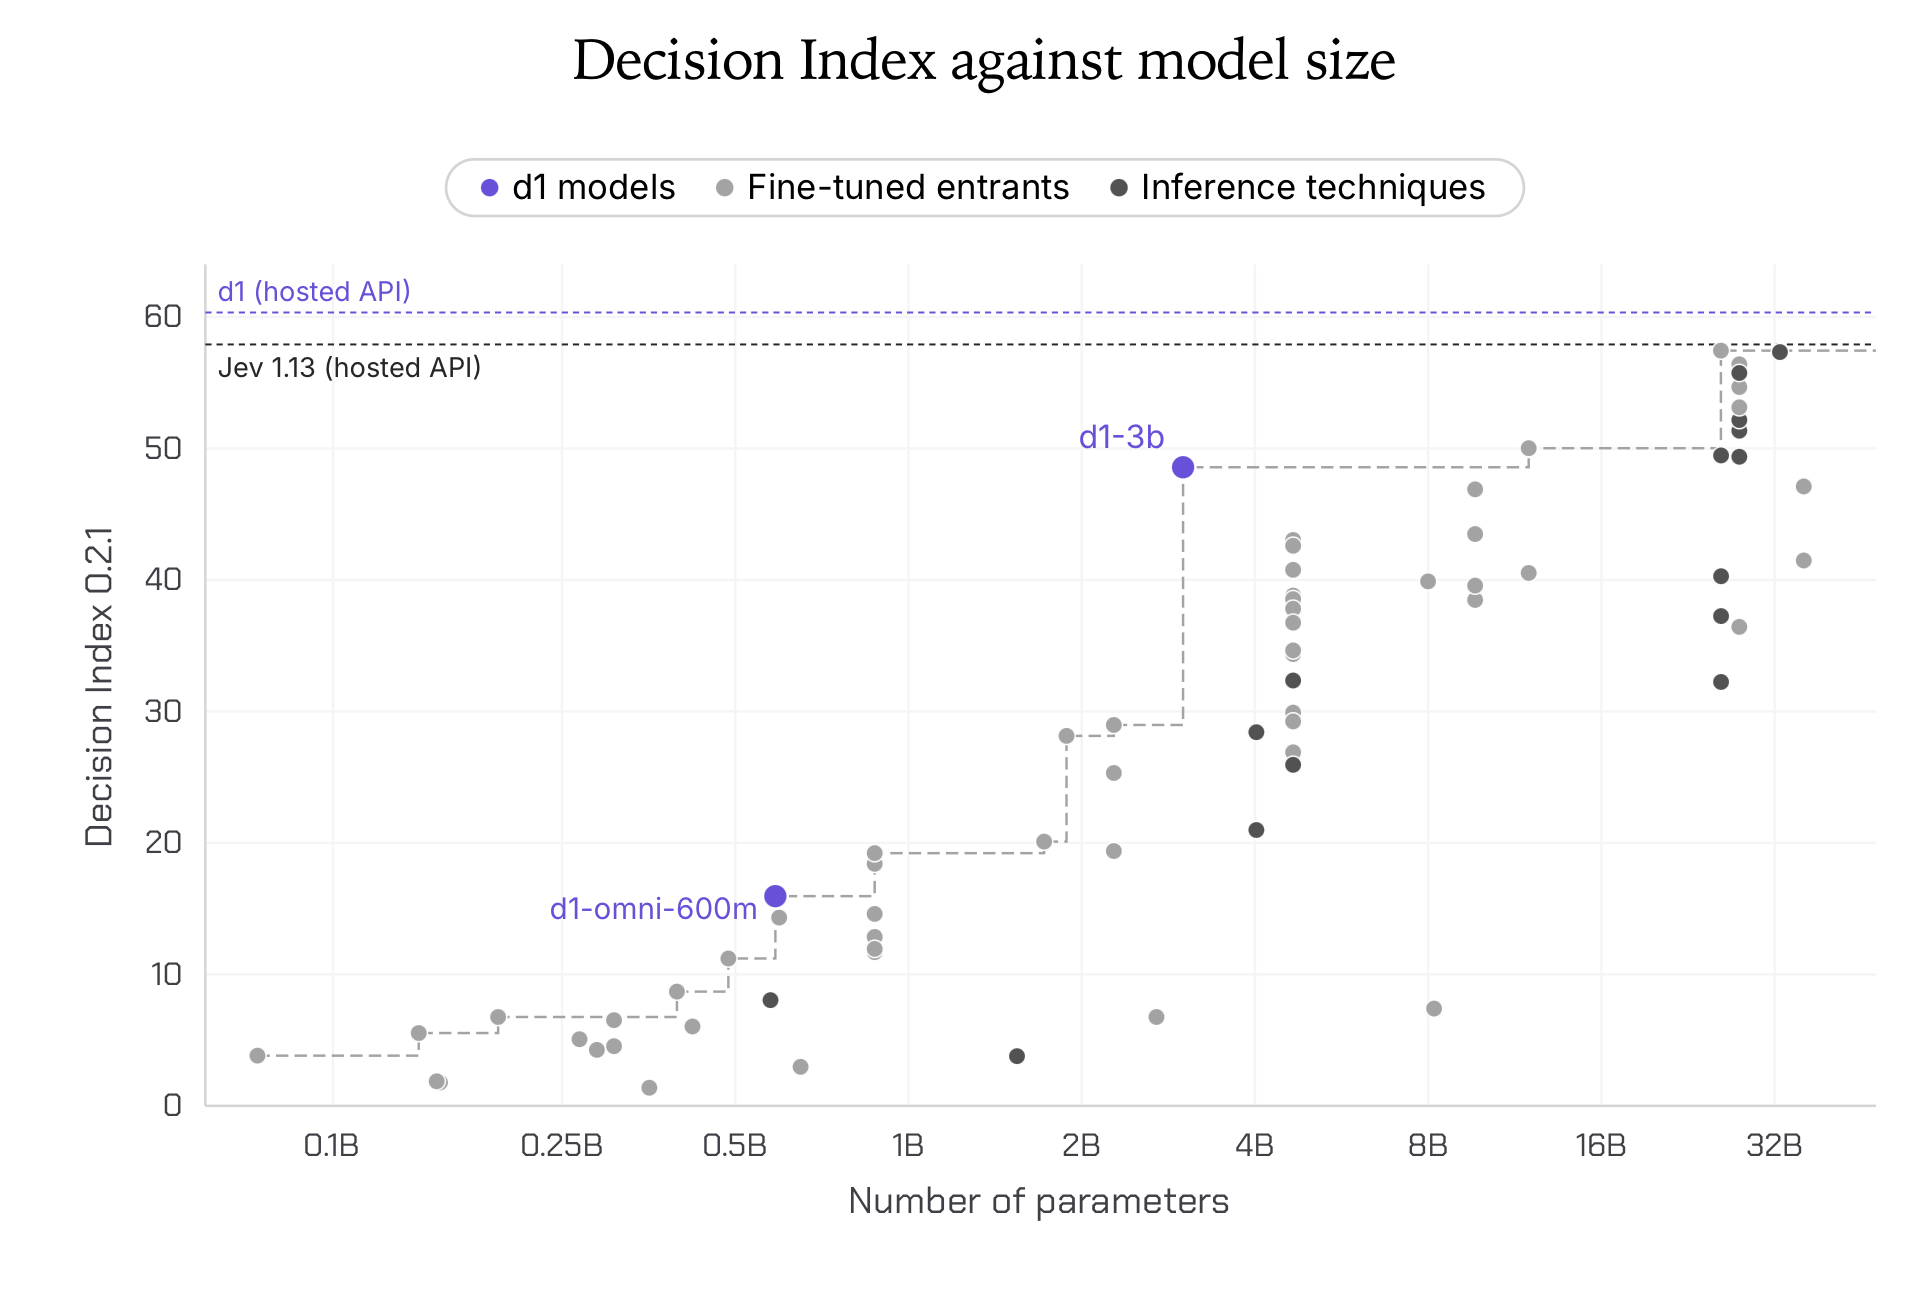
Liquid AI has released d1-3B and d1-omni-600M, two decision models designed to perform classification and extraction tasks in a single forward pass. These models move away from generative token output, delivering responses on edge hardware like the Jetson AGX Orin in under 50 milliseconds. The 3B parameter model handles text, vision, and audio, while the smaller 600M version targets footprint-constrained environments.
If you are building structured data pipelines or classification tasks on the edge, this is worth testing to avoid the overhead of a full generative LLM. However, be aware that you must use trust_remote_code for the custom inference architecture, which introduces a dependency on their specific implementation. It is not a general-purpose conversational agent, so look elsewhere if you need chat capabilities.


Leave a comment