Ollaya runs open decision models locally via a Jev-compatible API

23 10 2026
Ollaya runs open decision models locally via a Jev-compatible API

Ollaya is a self-hosted inference daemon and CLI that runs open decision models locally without generating text. Using a single forward pass, it evaluates states like JSON messages against typed questions to return calibrated probabilities in milliseconds. On an RTX 5090, the recommended 4B model processes five questions in 113 ms, while CPU-friendly alternatives take around half a second.

It is worth installing if you are already using TypeSafe workflows and want to run models locally under an Apache-2.0 license. However, it is built exclusively for structured classification and routing rather than text generation, so it will not replace a standard LLM backend. If your application relies on unstructured output or long-form reasoning, skip it.

more: https://github.com/ollaya-dev/ollaya

my other side: ivo.blogspot.com


Hugging Face Trainium compatibility lookup space

23 10 2026
Hugging Face Trainium compatibility lookup space

David Corvoysier documented a Hugging Face Space that checks whether popular text and vision models run on AWS Trainium instances using the torch-neuronx backend. The tool reports pass-fail status, core counts, memory usage, and wall time across up to sixteen Trainium2 cores. It also provides the exact installation recipes and python scripts used for each test.

It is worth checking if you are deploying standard Transformers models on AWS custom silicon and want to avoid blind compilation failures. The catch is that tests are currently limited to generation tasks fitting on four devices, and a pass only verifies basic output rather than production throughput or long-context stability.

more: https://huggingface.co/blog/torch-neuronx-model-support

my other side: ivo.blogspot.com


Using Database State as RL Rewards

23 10 2026
Using Database State as RL Rewards

Microsoft and Hugging Face released ThinkingBox-Training, an open-source codebase for using terminal database states as binary reward functions during agent post-training. By filtering tasks using an offline policy-relative difficulty measure and applying 50 steps of GRPO, they fine-tuned Qwen3.8-27B to increase average success from 51.7% to 60.8%. Tasks completed successfully across all twenty test attempts rose from 38 to 107.

It is worth adopting if you are already running GRPO loops and need objective, non-LLM-as-a-judge verification for backend tool use. The catch is that you need a reliable execution sandbox for your target databases and enough compute to filter out tasks that are either too easy or hopeless for your base model. Skip this if your agent workflows do not involve persistent state changes or complex multi-step backend transactions.

more: https://huggingface.co/blog/microsoft/thinkingbox-training

my other side: ivo.blogspot.com


Extend Agents CLI for LangChain and Custom Deploy Policies

22 10 2026
Extend Agents CLI for LangChain and Custom Deploy Policies

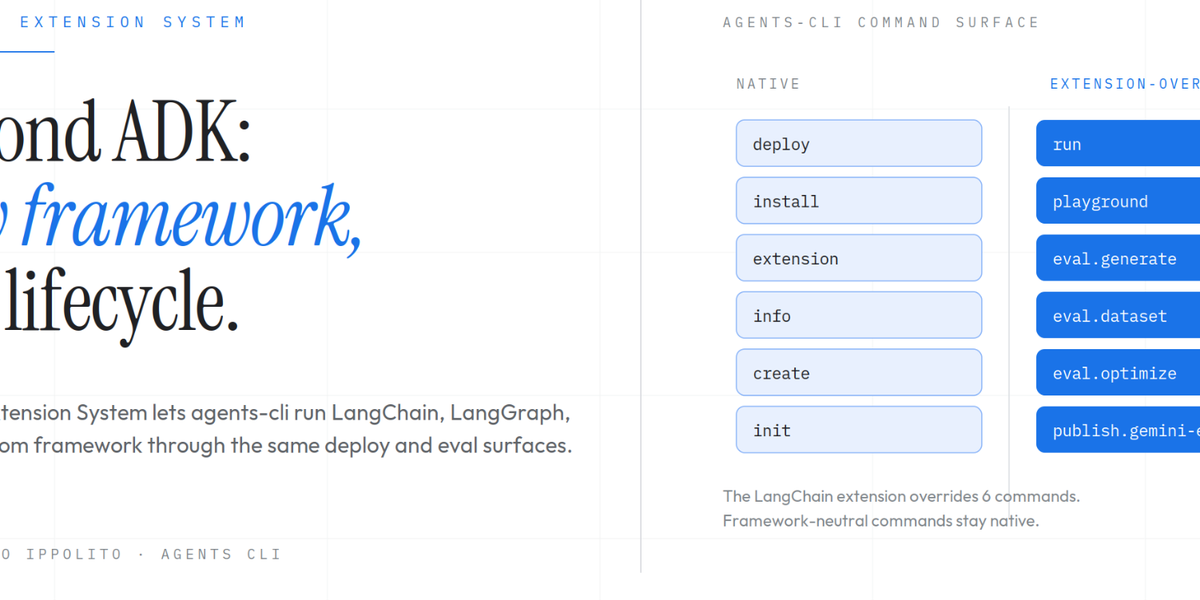
Google's Agents CLI, first launched at Cloud Next '26, now ships with an Extension System as of version 1.5.0. This allows developers to override existing commands or add new ones without forking the tool. Version 1.8.0 includes a first-party LangChain extension, enabling a full agent development lifecycle (scaffold, run, deploy, evaluate) with LangChain agents. It also facilitates custom policies, like an SBOM scan wrapping the deploy command.

This is a welcome evolution for agent development, especially for teams working across multiple frameworks or needing to enforce enterprise-specific governance. If you've been avoiding Agents CLI due to its initial ADK opinionation, this update makes it far more versatile. The limitation is that while the system is flexible, building complex custom extensions for unique policies will still require internal development effort.

more: https://developers.googleblog.com/powering-the-agent-development-lifecycle-with-any-framework-from-adk-to-langchain-and-beyond/


IBM Granite Time-Series Ensemble for Python

22 10 2026
IBM Granite Time-Series Ensemble for Python

IBM released granite-tsfm 0.3.11, a Python package that bundles four pre-trained time-series models into a single ensemble interface. Calling QuantileEnsembleForecaster.from_pretrained downloads the member checkpoints from Hugging Face and returns both point forecasts and quantile outputs without requiring prior training on your data. The default recipe pools forecasts in probability space using fixed equal weights.

It is worth testing if you need zero-shot probabilistic forecasting across mixed industrial or retail signals and want to skip the overhead of training model weights. The catch is that the first run takes extra time to download all four underlying architectures at runtime, and the package is not built for custom streaming pipelines. You should stick to a single tuned model if you already have clean data and well-defined domains.

more: https://huggingface.co/blog/ibm-research/granite-timeseries-ensemble-r1

my other side: ivo.blogspot.com


Ovis: browser and phone client for herdr

22 10 2026
Ovis: browser and phone client for herdr

Ovis is a PWA and browser interface for the herdr agent manager, letting you monitor and reply to Claude Code, Codex, and other CLI agent sessions from your phone or desktop. It gives you a chat-to-terminal toggle, push alerts, a mobile keyboard modifier bar, and voice dictation running over a Tailscale connection. The installer requires macOS or glibc Linux, Bun 1.4+, Node 18+, and herdr 0.9.0+.

It is worth setting up if you already run herdr and want to manage long-running local coding sessions away from your desk without dealing with raw SSH. The catch is its strict environment requirements and the security footprint of exposing local agent terminals via Tailscale serve. Skip it if you do not use herdr or prefer managing tmux sessions manually.

more: https://github.com/devswha/ovis

my other side: ivo.blogspot.com


Profiling TorchNeuron on AWS Trainium

21 10 2026
Profiling TorchNeuron on AWS Trainium

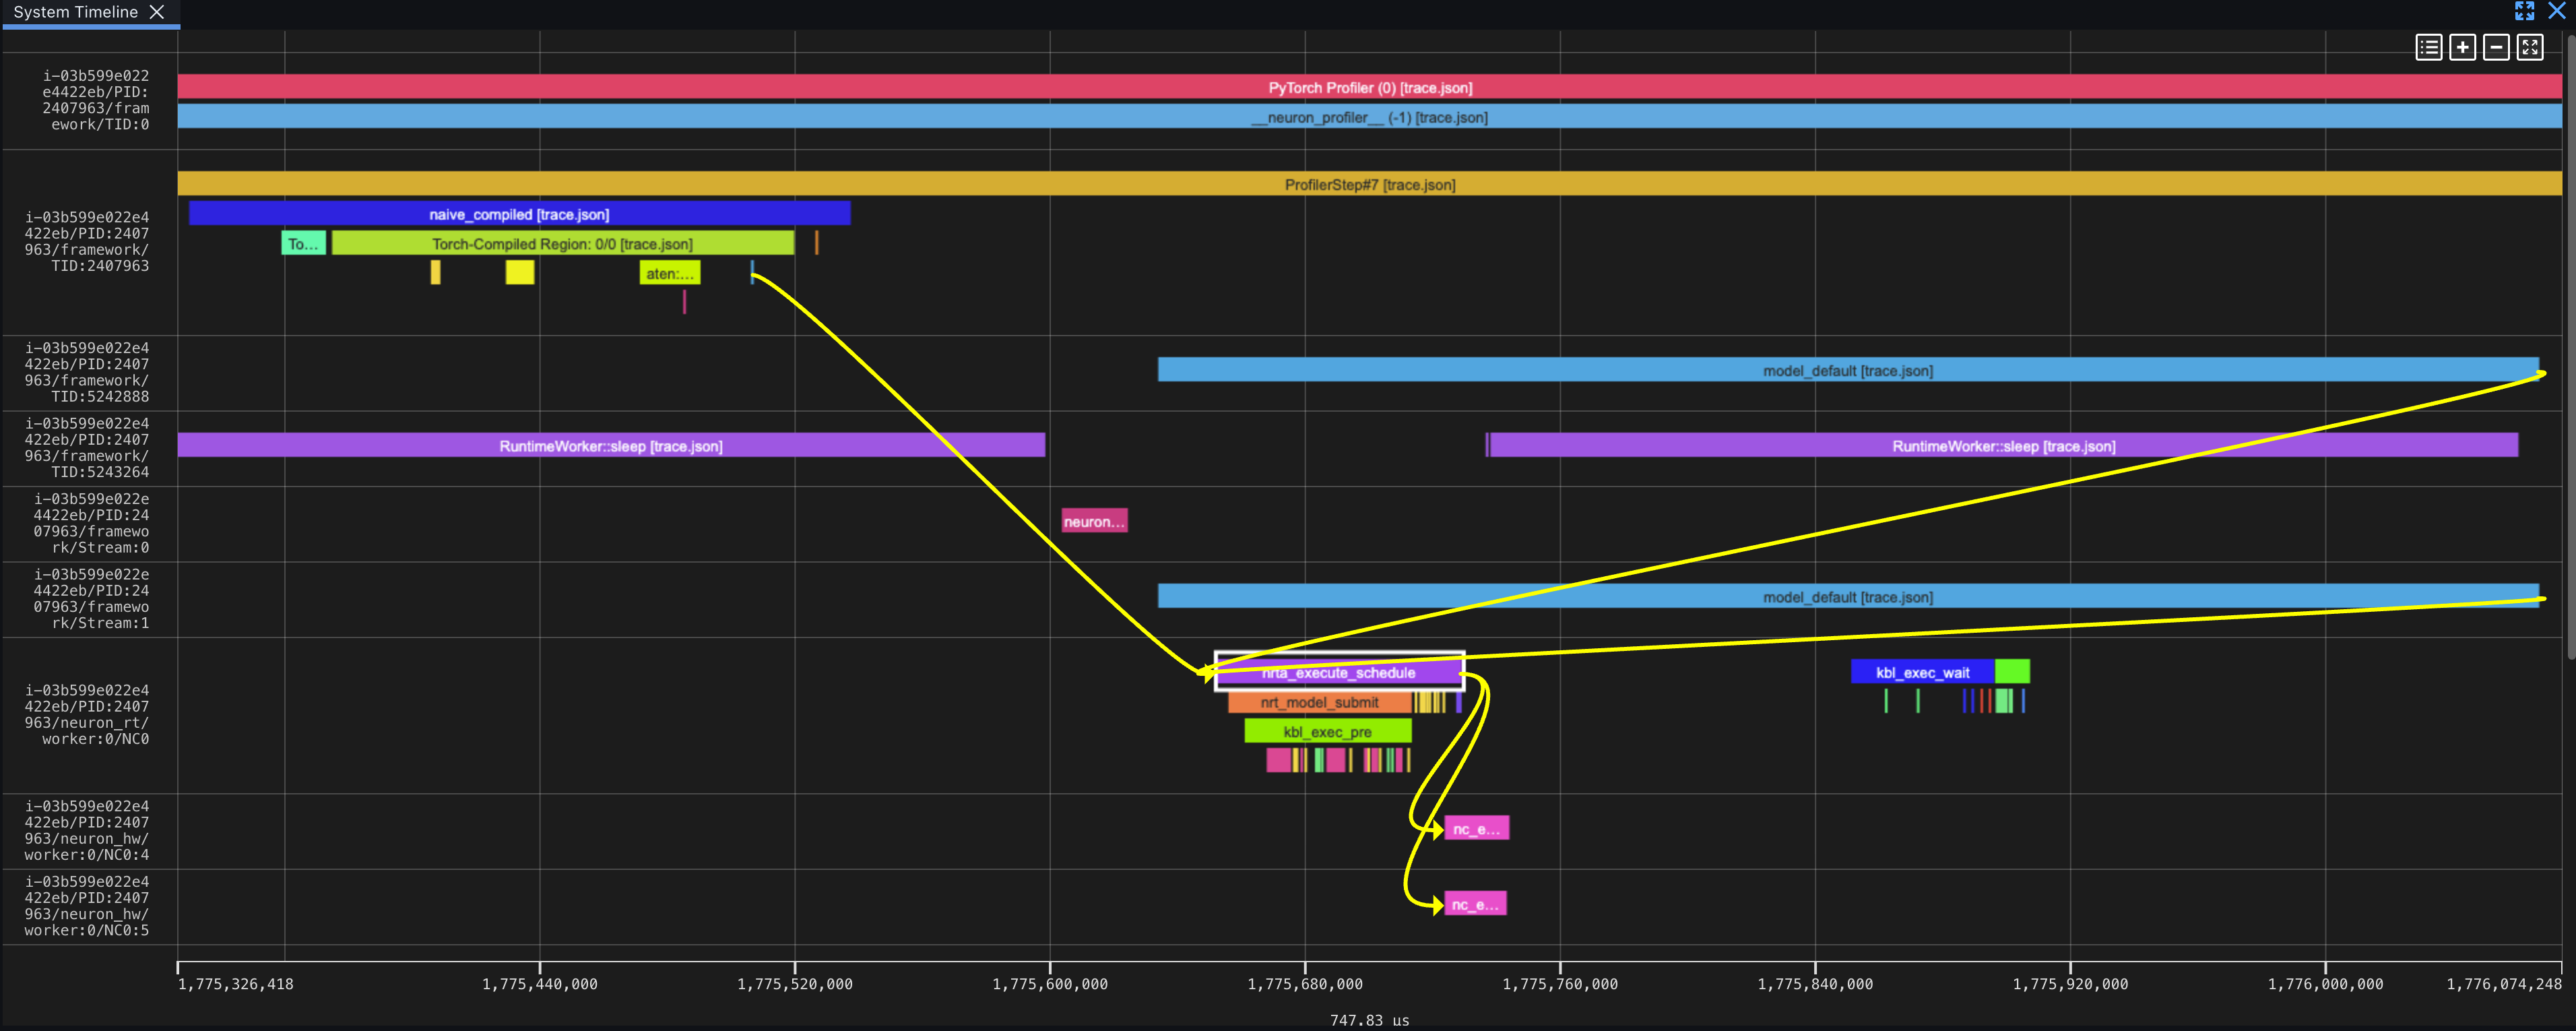
Hugging Face's guide covers system-level performance analysis for AWS Trainium using TorchNeuron and the NeuronProfiler API. It walks through setting up NeuronConfig, capturing device and runtime traces, and analyzing an RMSNorm implementation using Neuron Explorer. The post shows how to wire standard PyTorch profiler steps into the PrivateUse1 backend without modifying core model code.

It is worth reading if you are deploying models on Trainium and need to move past guesswork to trace actual hardware bottlenecks. The catch is that it only covers the mechanics of capturing a trace for a single tiny operation rather than diagnosing a full production model. If you are not targeting AWS silicon, you can safely skip it.

more: https://huggingface.co/blog/amazon/profiling-torchneuron-part-1

my other side: ivo.blogspot.com


FairStress evaluation of LLM fairness

20 10 2026
FairStress evaluation of LLM fairness

FairStress is a 300‑scenario benchmark spanning 29 domains, hosted on Hugging Face, designed to measure how LLMs respond to demographic changes and adversarial prefixes. It integrates directly into Olmo‑eval, so you can run it on any open‑weight model or GPT‑style API with a single command. The dataset includes explicit, implicit, and no‑identity versions of each scenario to test subtle bias.

If you’re evaluating model fairness beyond surface decisions, FairStress gives a more nuanced view than standard parity checks. It does not cover equity‑based fairness or long‑term impact analysis, and its adversarial prefixes are manually curated, so you’ll need to supplement it for deeper coverage. It’s best suited for research labs or teams with evaluation pipelines, not for quick production testing.

more: https://huggingface.co/blog/allenai/fairstress

my other side: ivo.blogspot.com


Project Maya runs 300B MoE models locally

20 10 2026
Project Maya runs 300B MoE models locally

Project Maya is a local inference engine for massive Mixture-of-Experts models like GLM-5.3-Flash and DeepSeek-V4.1. It offloads inactive experts to system RAM and NVMe SSDs, allowing 748B parameter models to run on single GPUs or multi-GPU setups. The API is compatible with OpenAI and Anthropic standards, supporting tool calls and concurrent requests.

This is worth trying if you have high-end local hardware and need private, low-latency LLM access without cloud costs. The catch is the steep hardware floor: expect to use 100GB+ of combined VRAM and RAM for usable performance. It is not a solution for standard consumer laptops or low-memory systems.

more: https://github.com/mw00/project-maya

my other side: ivo.blogspot.com


AnyLanguageModel 1.0 brings unified inference to Swift

20 10 2026
AnyLanguageModel 1.0 brings unified inference to Swift

Mattt and the team at Hugging Face have released version 1.0 of AnyLanguageModel, a Swift library that acts as a drop-in replacement for Apple's Foundation Models framework. By changing a single import statement, you can swap between the on-device system model, local runtimes like MLX and llama.cpp, and hosted APIs using identical session code. It also includes support for guided generation, streaming tool calls, and model downloads via companion packages.

If you are already writing Swift apps and want to experiment with local weights or abstract away multiple inference backends without rewriting your session logic, this saves you real boilerplate. The catch is that managing memory for open-weight models on user hardware remains messy, and relying on a third-party wrapper means you are coupling your inference layer directly to Hugging Face's ecosystem.

more: https://huggingface.co/blog/anylanguagemodel-1-0

my other side: ivo.blogspot.com