Peach: self-hosted media manager for adult collections

23 10 2026
Peach: self-hosted media manager for adult collections

Peach is an open-source, local-first application designed to organize adult video collections scattered across local disks and mounted cloud storage like 115, PikPak, or OneDrive. It combines a grid-based browser, metadata scrapers, and subtitle search into a single interface that runs on Windows, macOS, or Docker. The software reads existing NFO files and folder structures without modifying your original files while pulling in missing covers, tags, and creator updates from supported platforms.

It is worth a look if you are tired of manual sorting and want a unified local UI with browser extension integration for cloud downloads. The catch is that it remains an immature desktop tool with unsigned binaries, no official mobile app beyond web access, and requires you to bring your own cloud accounts and storage. Skip it if you just want a standard media server like Plex or Jellyfin for mainstream video.

more: https://github.com/peach-mitao/peach

my other side: ivo.blogspot.com


Doory: A self-hosted browser-based design editor

23 10 2026
Doory: A self-hosted browser-based design editor

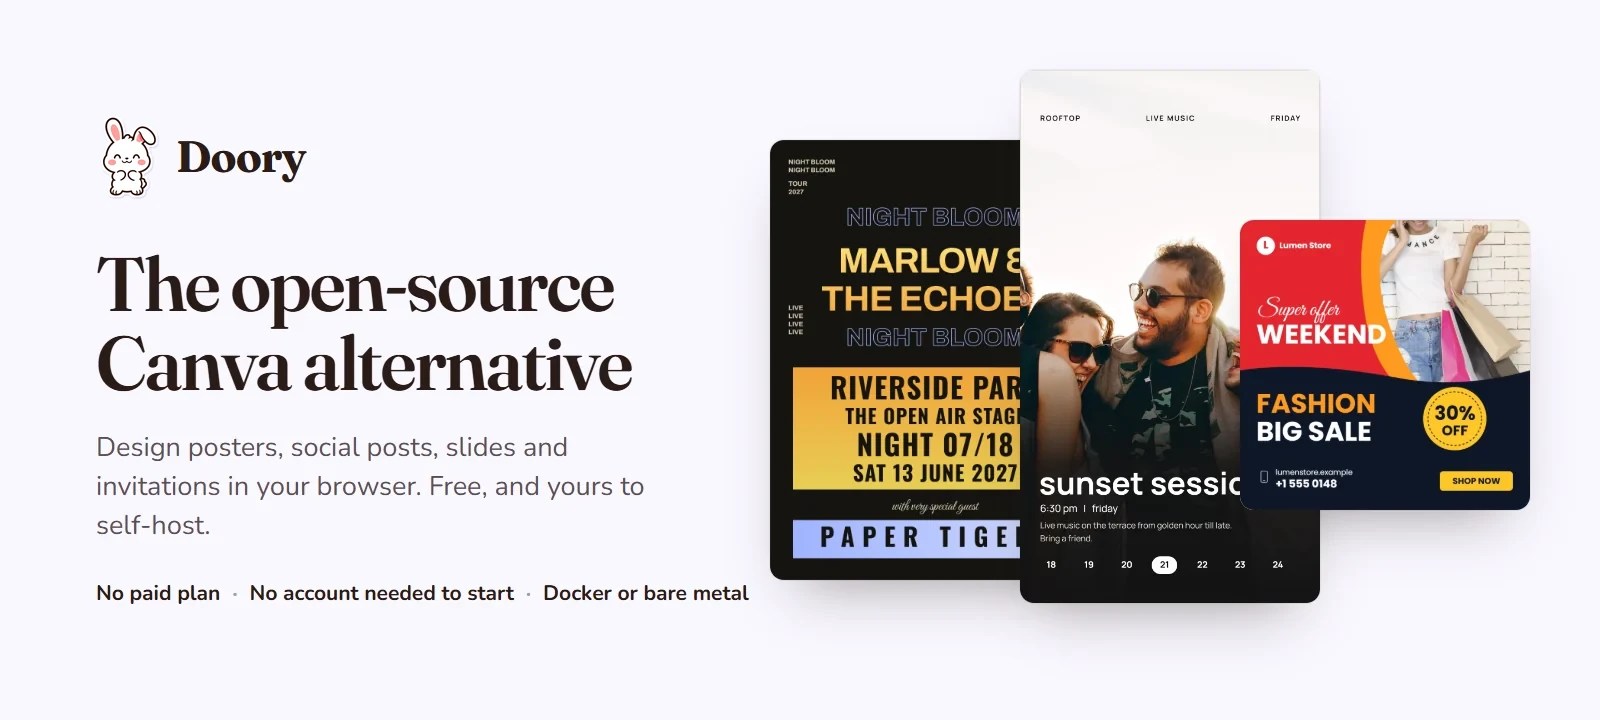
Doory is a Dockerized, open-source design tool built on Django and FabricJS that replaces cloud-based options like Canva. It runs on your own hardware and handles everything from basic image cropping and PDF exports to animations, video generation, and real-time co-editing. The project also includes an optional Model Context Protocol server so AI assistants like Claude can directly generate and modify your designs.

It is worth setting up if you need an internal graphic editor without third-party data sharing, but the current template library is tiny at just ten starter items. You will have to seed your own fonts, icons, and templates before it is genuinely useful for a team. Skip it if you are looking for a drop-in replacement with a massive pre-existing asset library.

more: https://github.com/shaongitbd/doory

my other side: ivo.blogspot.com


Extend Agents CLI for LangChain and Custom Deploy Policies

22 10 2026
Extend Agents CLI for LangChain and Custom Deploy Policies

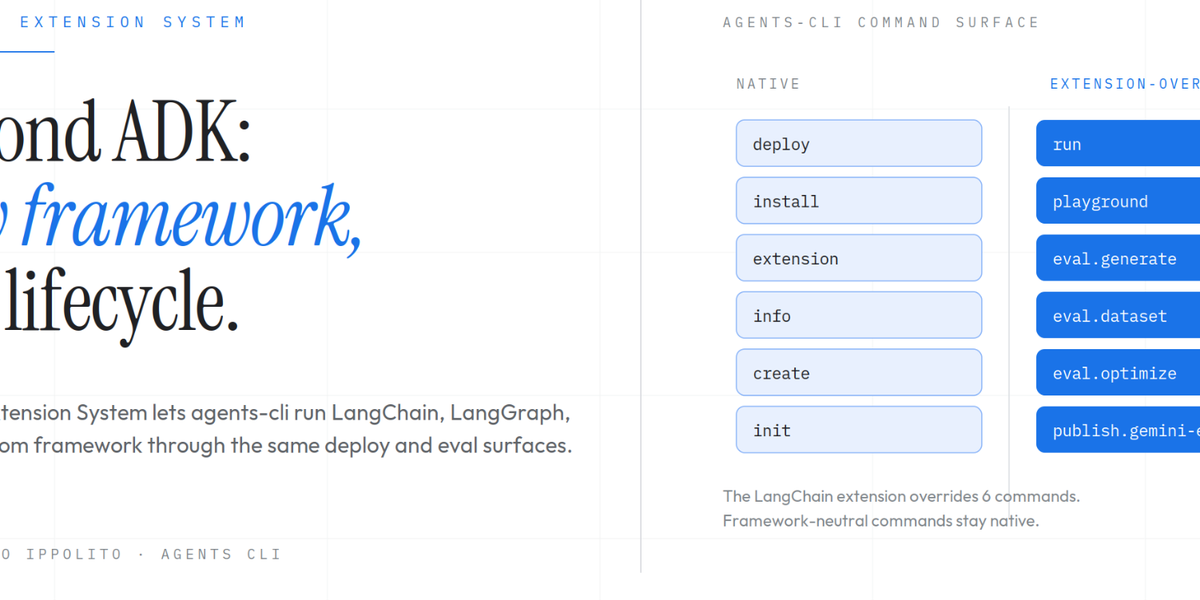
Google's Agents CLI, first launched at Cloud Next '26, now ships with an Extension System as of version 1.5.0. This allows developers to override existing commands or add new ones without forking the tool. Version 1.8.0 includes a first-party LangChain extension, enabling a full agent development lifecycle (scaffold, run, deploy, evaluate) with LangChain agents. It also facilitates custom policies, like an SBOM scan wrapping the deploy command.

This is a welcome evolution for agent development, especially for teams working across multiple frameworks or needing to enforce enterprise-specific governance. If you've been avoiding Agents CLI due to its initial ADK opinionation, this update makes it far more versatile. The limitation is that while the system is flexible, building complex custom extensions for unique policies will still require internal development effort.

more: https://developers.googleblog.com/powering-the-agent-development-lifecycle-with-any-framework-from-adk-to-langchain-and-beyond/


IBM Granite Time-Series Ensemble for Python

22 10 2026
IBM Granite Time-Series Ensemble for Python

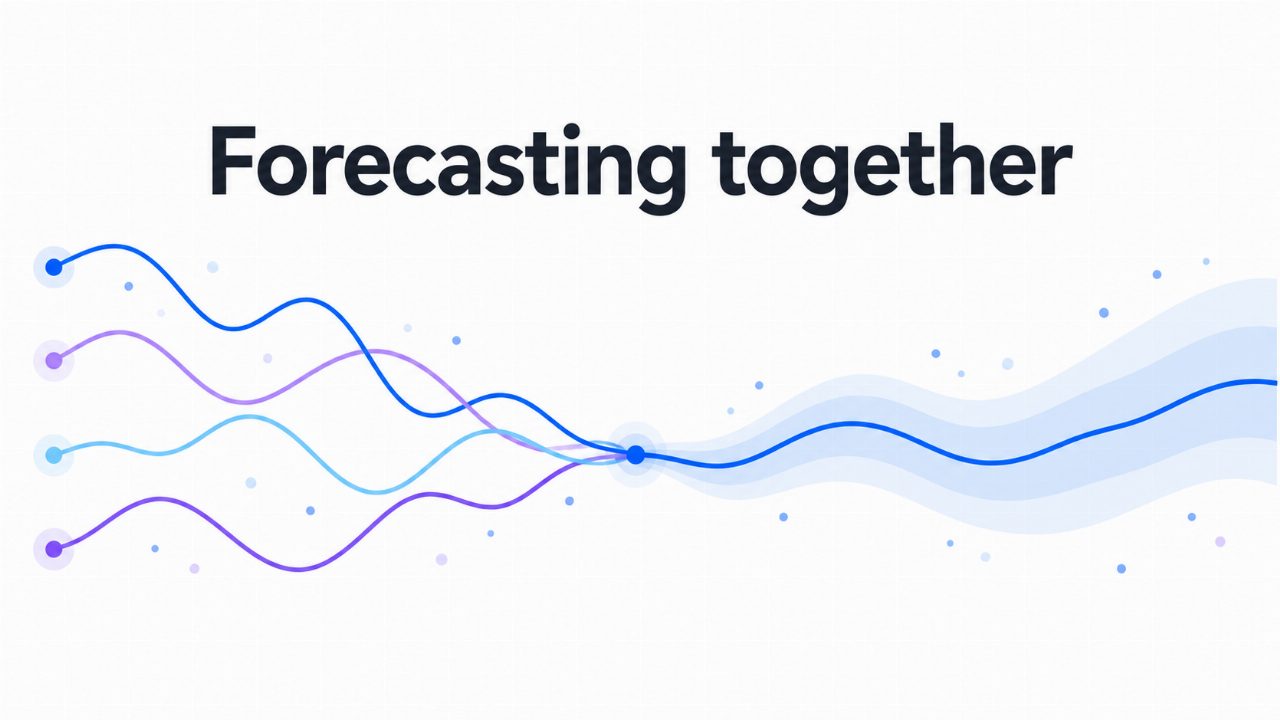
IBM released granite-tsfm 0.3.11, a Python package that bundles four pre-trained time-series models into a single ensemble interface. Calling QuantileEnsembleForecaster.from_pretrained downloads the member checkpoints from Hugging Face and returns both point forecasts and quantile outputs without requiring prior training on your data. The default recipe pools forecasts in probability space using fixed equal weights.

It is worth testing if you need zero-shot probabilistic forecasting across mixed industrial or retail signals and want to skip the overhead of training model weights. The catch is that the first run takes extra time to download all four underlying architectures at runtime, and the package is not built for custom streaming pipelines. You should stick to a single tuned model if you already have clean data and well-defined domains.

more: https://huggingface.co/blog/ibm-research/granite-timeseries-ensemble-r1

my other side: ivo.blogspot.com


Ovis: browser and phone client for herdr

22 10 2026
Ovis: browser and phone client for herdr

Ovis is a PWA and browser interface for the herdr agent manager, letting you monitor and reply to Claude Code, Codex, and other CLI agent sessions from your phone or desktop. It gives you a chat-to-terminal toggle, push alerts, a mobile keyboard modifier bar, and voice dictation running over a Tailscale connection. The installer requires macOS or glibc Linux, Bun 1.4+, Node 18+, and herdr 0.9.0+.

It is worth setting up if you already run herdr and want to manage long-running local coding sessions away from your desk without dealing with raw SSH. The catch is its strict environment requirements and the security footprint of exposing local agent terminals via Tailscale serve. Skip it if you do not use herdr or prefer managing tmux sessions manually.

more: https://github.com/devswha/ovis

my other side: ivo.blogspot.com


pgrundev/pgx: Multi-tenant Postgres runtime for short-lived databases

22 10 2026
pgrundev/pgx: Multi-tenant Postgres runtime for short-lived databases

pgx is a v0.1.0 Rust runtime that packs a thousand isolated PostgreSQL-compatible databases into roughly 150 megabytes of memory on a single machine. It mints warm databases in about six milliseconds and uses ZFS copy-on-write to branch a ten-gigabyte template in under a second. It replaces the pattern of spinning up separate Docker containers or server processes for test suites, CI jobs, and agent sandboxes.

It is worth testing if your workflow creates and destroys databases constantly, though it requires ZFS on Linux to get the fast copy-on-write storage cloning. It is built strictly for ephemeral development environments and agent workloads rather than long-running production primaries. You should skip it if your stack relies on database extensions or specific PostgreSQL features that fall outside its core wire protocol and regression test coverage.

more: https://github.com/pgrundev/pgx

my other side: ivo.blogspot.com


Rubix: A 42KB x86-64 assembly compiler

22 10 2026
Rubix: A 42KB x86-64 assembly compiler

Rubix is a systems programming language with a compiler written entirely in pure x86-64 assembly. The resulting binary is roughly 42 kilobytes, has zero libc or external dependencies, and compiles source files in under a millisecond. It handles multi-file imports, heap allocation, and standard control flow while targeting Linux, Windows, and macOS.

It is an impressive technical exercise if you want to study low-level compilation and x86-64 mechanics without the weight of LLVM or C. However, it is strictly tied to the x86-64 architecture and lacks the ecosystem maturity required for production software. Skip it unless you specifically want to hack on bare-metal assembly tooling.

more: https://github.com/tek-sys-hub/Rubix-lang

my other side: ivo.blogspot.com


Profiling TorchNeuron on AWS Trainium

21 10 2026
Profiling TorchNeuron on AWS Trainium

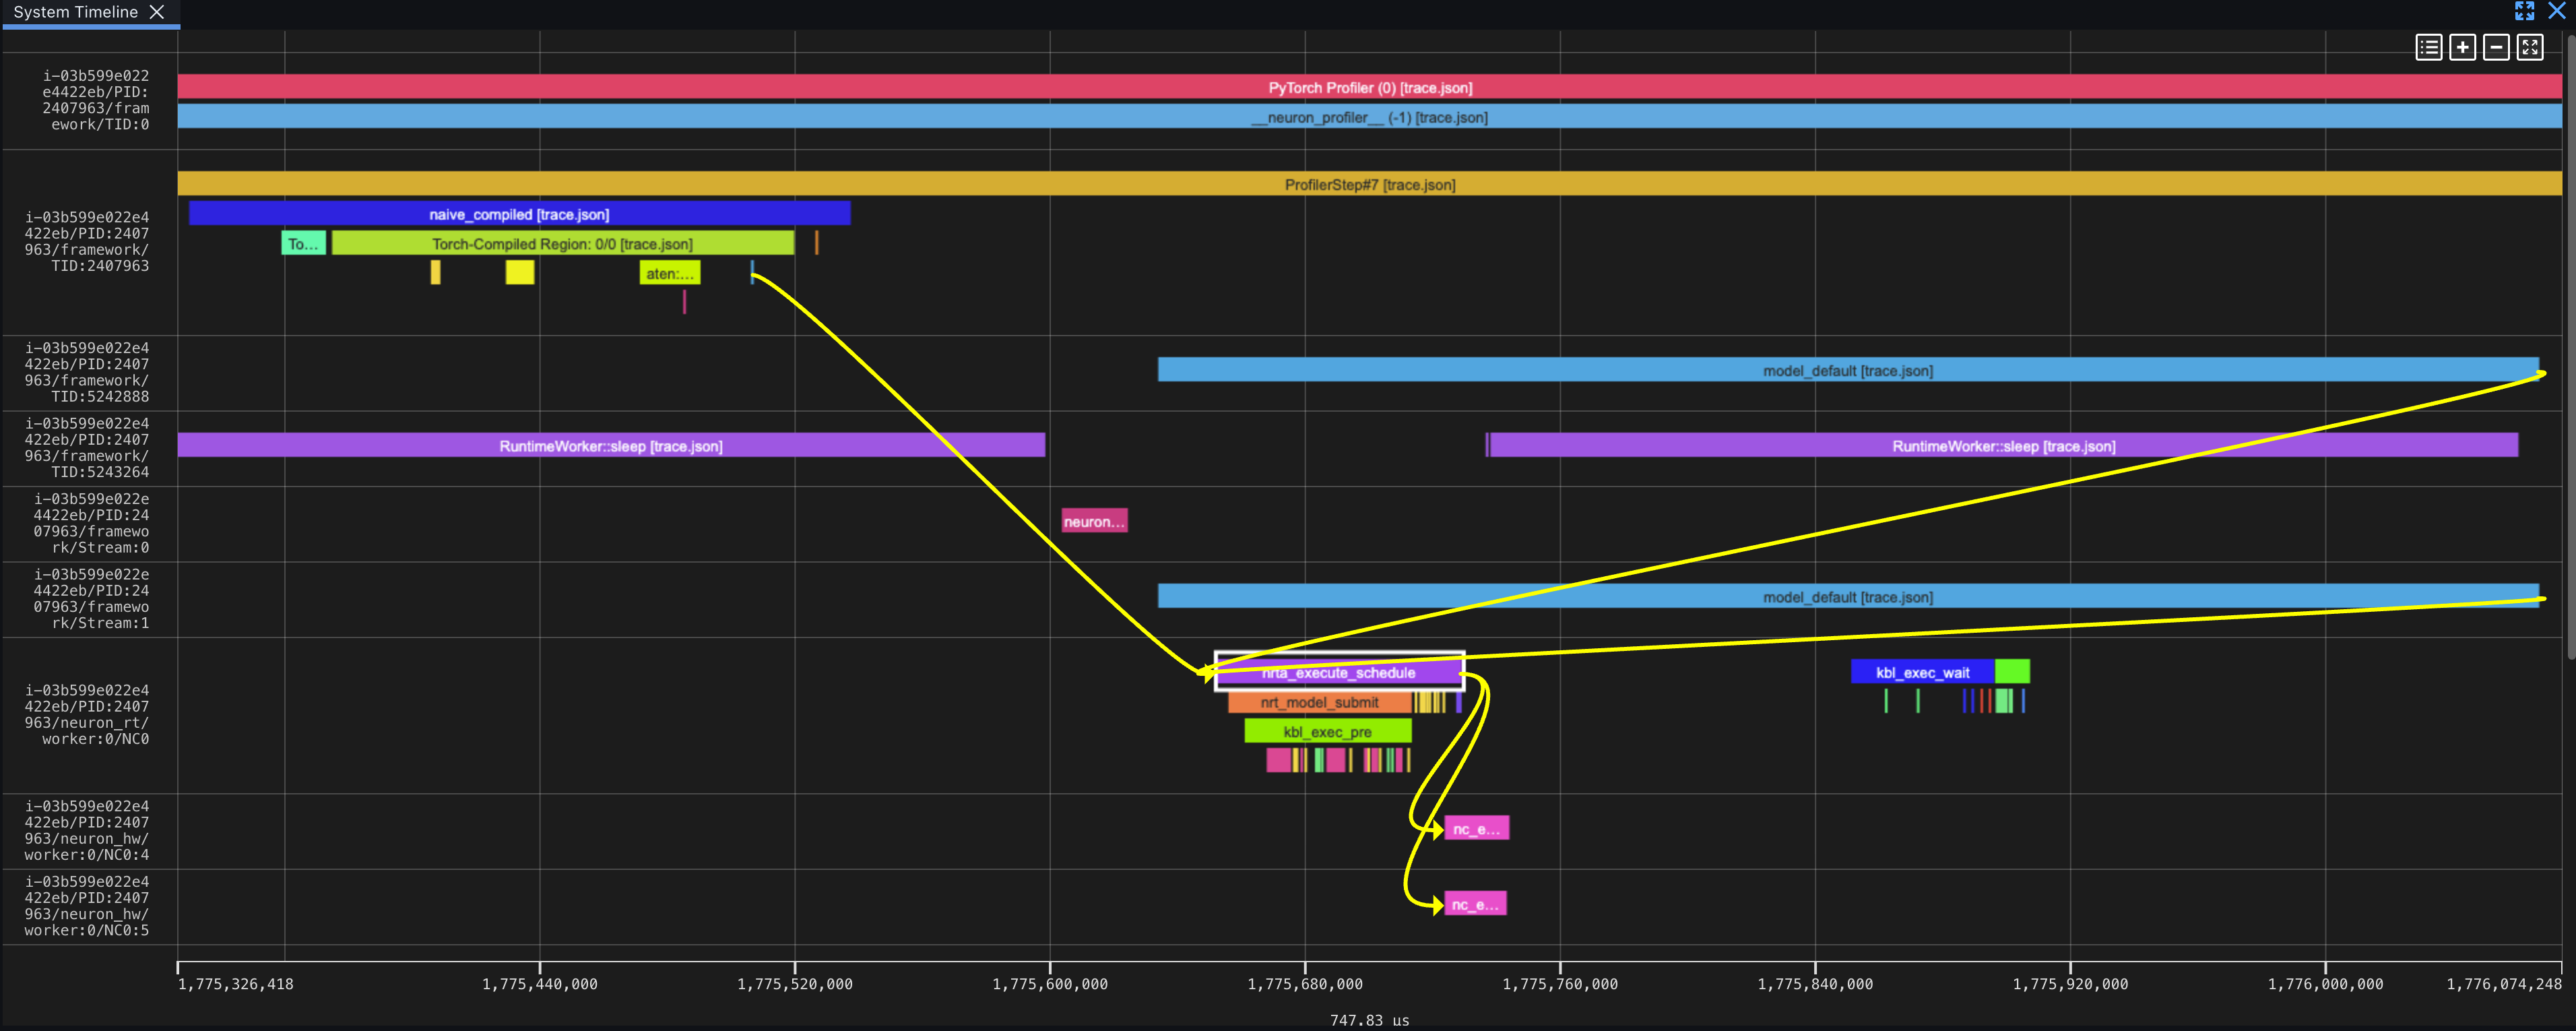
Hugging Face's guide covers system-level performance analysis for AWS Trainium using TorchNeuron and the NeuronProfiler API. It walks through setting up NeuronConfig, capturing device and runtime traces, and analyzing an RMSNorm implementation using Neuron Explorer. The post shows how to wire standard PyTorch profiler steps into the PrivateUse1 backend without modifying core model code.

It is worth reading if you are deploying models on Trainium and need to move past guesswork to trace actual hardware bottlenecks. The catch is that it only covers the mechanics of capturing a trace for a single tiny operation rather than diagnosing a full production model. If you are not targeting AWS silicon, you can safely skip it.

more: https://huggingface.co/blog/amazon/profiling-torchneuron-part-1

my other side: ivo.blogspot.com


FairStress evaluation of LLM fairness

20 10 2026
FairStress evaluation of LLM fairness

FairStress is a 300‑scenario benchmark spanning 29 domains, hosted on Hugging Face, designed to measure how LLMs respond to demographic changes and adversarial prefixes. It integrates directly into Olmo‑eval, so you can run it on any open‑weight model or GPT‑style API with a single command. The dataset includes explicit, implicit, and no‑identity versions of each scenario to test subtle bias.

If you’re evaluating model fairness beyond surface decisions, FairStress gives a more nuanced view than standard parity checks. It does not cover equity‑based fairness or long‑term impact analysis, and its adversarial prefixes are manually curated, so you’ll need to supplement it for deeper coverage. It’s best suited for research labs or teams with evaluation pipelines, not for quick production testing.

more: https://huggingface.co/blog/allenai/fairstress

my other side: ivo.blogspot.com


Project Maya runs 300B MoE models locally

20 10 2026
Project Maya runs 300B MoE models locally

Project Maya is a local inference engine for massive Mixture-of-Experts models like GLM-5.3-Flash and DeepSeek-V4.1. It offloads inactive experts to system RAM and NVMe SSDs, allowing 748B parameter models to run on single GPUs or multi-GPU setups. The API is compatible with OpenAI and Anthropic standards, supporting tool calls and concurrent requests.

This is worth trying if you have high-end local hardware and need private, low-latency LLM access without cloud costs. The catch is the steep hardware floor: expect to use 100GB+ of combined VRAM and RAM for usable performance. It is not a solution for standard consumer laptops or low-memory systems.

more: https://github.com/mw00/project-maya

my other side: ivo.blogspot.com